
Season 1 – Episode 49 – Ethical Considerations for Vibe Coding
Discusses ethical considerations for vibe coding, which is the practice of prompting AI tools to generate code.
Notes
To view this episode’s notes, simply click on the “More Info” button on the player.
Podcast Chapters
Click to expand/collapse
To easily navigate through our podcast, simply click on the ☰ icon on the player. This will take you straight to the chapter timestamps, allowing you to jump to specific segments and enjoy the parts you’re most interested in.
- Episode Introduction and Disclaimer (00:00:03) Daniel introduces Shreya Kumar and the discussion of ethical considerations for vibe coding, then provides the podcast’s educational and legal disclaimer.
- Shreya Kumar’s Background in Software Engineering and Ethics (00:01:00) Shreya describes her experience across industry and academia and her interest in software development’s human costs, professional responsibility, and ethical accountability.
- Defining Vibe Coding and AI-Assisted Software Development (00:02:08) The conversation defines vibe coding as using goals and outcomes to direct AI tools, distinguishes it from other forms of AI-assisted development, and contrasts it with traditional software engineering.
- Appropriate and Risky Uses of Vibe Coding (00:05:20) Shreya explains how vibe coding can accelerate prototypes and low-risk projects while emphasizing that high-stakes systems still require careful planning, testing, security, and human oversight.
- Ethical Concerns in Deploying AI-Generated Code (00:07:46) The discussion covers security vulnerabilities, hallucinated dependencies, poor maintainability, data privacy, transparency, biased systems, and the broader human impact of replacing workers with AI tools.
- The Air Canada Chatbot and Real-World Accountability (00:08:38) Shreya uses the Air Canada bereavement-fare case to illustrate how even seemingly low-risk AI tools can make consequential claims for which an organization may be held responsible.
- Mid-Episode Message About On Campus (00:11:09) Ed Butch briefly promotes CITI Program’s On Campus podcast and invites listeners to explore new monthly episodes before the main discussion resumes.
- Shared Responsibility for AI-Generated Systems (00:11:30) Shreya discusses how responsibility should be distributed among individual developers and users, deploying organizations, and AI tool providers, while noting that current laws do not clearly assign accountability.
- Risk-Based Regulation and Organizational Governance (00:13:42) The conversation examines the EU AI Act’s risk categories, the limits of regulatory minimums, and the need for organizations to maintain software architecture governance, compliance, and awareness of their code bases.
- Developer Obligations for Reviewing and Maintaining Code (00:17:12) Shreya explains that developers retain the same responsibilities they had before generative AI, including comprehensive specifications, test-driven development, architectural planning, documentation, maintenance, and close review of technical debt.
- Skills and Resources for Responsible AI-Assisted Development (00:19:58) Shreya discusses how AI can shorten development timelines without replacing foundational software engineering knowledge, human judgment, testing, usability review, or the ability to recognize when a system is wrong.
- Using Diagrams to Understand Vibe-Coded Systems (00:23:27) Shreya describes reverse-engineering AI-generated systems through class diagrams, swim lane diagrams, and architectural review so developers can compare what was built with what should have been built.
- Episode Closing and Tech Ethics Training Promotion (00:24:20) Daniel thanks Shreya, encourages listeners to explore CITI Program’s podcasts, courses, and webinars, highlights the Tech Ethics Training Solution, and recognizes the production team.
Episode Transcript
Click to expand/collapse
Daniel Smith: Welcome to On Tech Ethics with CITI Program. Today, I’m going to speak with Shreya Kumar, who is an associate teaching professor in computer science and engineering at the University of Notre Dame. Shreya works to ensure future software engineers understand their professional responsibilities, encouraging them to take ownership of their everyday decisions. Her mission is to prepare rigorously trained technologically proficient students who also critically evaluate the impact of their technology on society. In our conversation, we are going to discuss ethical considerations for vibe coding.
Before we get started, I want to quickly note that this podcast is for educational purposes only. It is not designed to provide legal advice or legal guidance. You should consult with your organization’s attorneys if you have questions or concerns about the relevant laws, regulations, and guidance that may be discussed in this podcast. In addition, the views expressed in this podcast are solely those of our guest. And on that note, welcome to the podcast, Shreya.
Shreya Kumar: Hi, Daniel. Thank you for having me.
Daniel Smith: It’s wonderful to have you. So I just very briefly introduced you, but can you tell us some more about yourself?
Shreya Kumar: Sure, sure. I’ve worked in industry in India, the UK, the US. And through all that journey, I’ve gone in and out of wanting to be in industry and wanting to be in academia. And then now I’ve been in academia for a while. And while I’ve been here, one of my interests has been to study how software engineering has been panning out, what are ways that we could improve it, what are ways that we could understand what really is the cost of software development, because largely it has been a human cost.
And more recently, this idea of, well, where does our ethical responsibility lie, and how can we make it easier for future engineers to actually be accountable to that and to actually think of practical ways that we can make better software for a better world? So that largely covers some of the things that I’ve been working on, but there’s tons of really cool things that the students do. So I get pulled into a lot of really fun directions.
Daniel Smith: Wonderful. So speaking of building better software, just building software in general, I mentioned that today we’re going to talk about vibe coding. And I think a lot of people might be familiar with what that means, but just to level set for everybody, can you start off by telling us what vibe coding is and how it differs from traditional software development or other forms of AI-assisted coding?
Shreya Kumar: Absolutely. This is a question that I’ve been pondering a ton, especially this year. The term vibe coding itself has been around for more than a year, but then every few weeks a new AI-assisted software development term comes up, and then that term gets outdated in a few weeks. So when we talk about vibe coding, sometimes I’ll be referring to this original definition by Andrej Karpathy who described it as using outcomes and goals to tell your AI tool what to build instead of actually reading the code line by line. And that type of vibe coding is well suited for rapid prototyping or making smaller projects that you use in real life.
But when it comes to software engineering, and to make things for production level software that would have user data and that would have real world impact on people, for those types of things, there’s other terms that get bandied about to indicate this is AI-assisted software development. Some of it is called agentic engineering, harness engineering, loop engineering. There are different ways to kind of cut up those terms, but popularly those terms get used interchangeably.
And then how is that different from traditional software engineering? In an oversimplified view of it, I’d say traditional software engineering uses tools to perform a certain set of actions to ensure that whatever software we deliver meets its specifications, regulatory compliance, rigorously tested standards that we ourselves develop, and then is maintainable, readable, and reusable. And those are things that vibe coding largely does not ensure.
And so software engineering with AI-assisted tools needs to still have all of that rigor, whereas vibe coding can be like, I want to make a really cool game or really cool visualization with some data that I have. And I know how to program, but I don’t want to spend a ton of time trying to look at the syntax for this thing. So I make a thing over a half hour period versus I make software for production, which still takes time and careful effort and planning.
To me, that is the major distinction, that we’ve gone from syntactic mastery, which was necessary and a barrier to access for any kind of system making. And that distinction is makers versus engineers. I think anyone can use generative AI tools to make systems with vibe coding, whereas software engineering is its own beast that applies so much more rigor and so many more standards to what actually reaches production.
Daniel Smith: You mentioned a few examples of how people are using vibe coding and where it can be useful. For example, with prototyping. I was wondering if you can walk through a specific example of where you’ve seen it be appropriate and useful, and then maybe an example where it would be more risky or harmful.
Shreya Kumar: One of the courses that I teach, we work with local nonprofits and really any organizations that we deem for social good. And then we try to build systems and projects for them. And that can range from a website or a data visualization dashboard or a full multi-feature app. And in the past, it used to take us several semesters and several team churns of students graduating and the new students taking on the project to deliver something simple, like an app with let’s say five, six major features.
Now I feel like we could cut down that delivery time to the actual building of it can just take a few hours, but then the understanding what needs to be built and making sure it’s safe and secure for them, that time can be cut down to just weeks. For low stakes, low risk projects where you’re not expecting half of humanity to use this tool, where you’re not working with sensitive data where the consequences of your system use are not dire, wherever we deem low risk and low impact, that’s a great use case for these because then we can even have domain experts make and validate the tools that they think are appropriate for their domain.
But anytime that domain also has larger real world impact, higher risk, like financial transactions, for anything that has actual measurable impact, I’d say vibe coding is maybe not the best choice. And I think initially I was under the impression that only those of us who are very careful and cautious about widespread deployment of these systems are of that opinion. But even the folks who invented the field really say that vibe coding is for getting to a working high fidelity prototype fast, but for high risk and high stakes deployment, you really need all of the steps and all of the human intervention and oversight that vibe coding doesn’t really necessitate. Anywhere that there’s risk, you’d want to say vibe coding’s a good MVP making tool, but not for the full development cycle.
Daniel Smith: So to hone in a bit on the risky uses of vibe coding, can you talk some more about the different ethical concerns that arise when people can build tools that could potentially be deployed without fully understanding the underlying code or going through the whole software development process?
Shreya Kumar: Oh, absolutely. And I think we’re already seeing use cases that fit exactly that high risk. We’re seeing so many systems being made and deployed that have unsecured API keys everywhere that have hallucinated data and hallucinated dependencies that expose security risks. We see systems that are buggy. And then when it’s time to fix those bugs, the software architecture hasn’t been constructed in a way that it’s easily scalable and maintainable.
There was this one recent case of Air Canada. It was using AI in a very small way that I would consider probably low risk. But an AI agent, which was like a chatbot, had hallucinated a fare policy around bereavement that didn’t actually exist. But because the AI chatbot was saying this, a judge held up that promise to say that, okay, well, I don’t care that you didn’t actually have this policy in the books. Your, a tool on your website. And they weren’t even using the AI tool to actually manage their system. It was what I would’ve then considered a harmless chatbot, but that’s not really true. Even chatbots can promise things and then you can be held to that.
So I think the ethical concerns arise from two things. One, the ways the systems actually interact in the world. Are we being careful with user data? Are we being careful with transparency and repeatability? Are we just taking really biased data and then making systems that are encoding that bias, and then nobody is looking closely at the systems to even examine it for that bias? There’s bias in people and data and systems everywhere. When you encode it into rules and rules that nobody’s really paying close attention to, that we’re just like, oh, it looks like it works, and it passes this one minimal unit test, then we get systems that are enforcing that bias even though that was never the intention of the makers.
So the bias in data and the way it treats differential user data. And then the other side of it is also the bias in the industry where now we’ve seen mass layoffs, and possibly an overcorrection by the industry to think, oh, we can just do the work of several hundred thousands of people with just AI tools. The human cost of all of their labor that allowed these tools to be created, whether it was their code that was used to train these tools, or their actual effort that was used to create the tools themselves, and then to say, oh, well, we’ve got what we want from you and now you are no longer a viable entity in our industry. So there are ethical concerns all over the place, all of the ways that humans are interacting with it in all the positive, creative, fun ways, and then also the really dire ways that we don’t even know that bias is being applied.
Ed Butch: I hope you’re enjoying this episode of On Tech Ethics. If you’re interested in important and diverse topics, the latest trends in the ever-changing landscape of universities, join me, Ed Butch, for CITI Program’s original podcast, On Campus. New episodes released monthly. Now, back to your episode.
Daniel Smith: So I think that the Air Canada case that you brought up brings up another interesting element of this, which is basically where responsibility lies. So when AI-generated code causes harm or introduces bias, creates security threats, hallucinates a policy, as was the case with Air Canada, how should we think about responsibility among the person using the AI, the organization who’s deploying the AI, and the provider who has created the underlying technology that’s allowed the organization or employees at the organization to create the AI tool?
Shreya Kumar: Well, that’s a really great question. And honestly, that’s kind of the question of our age right now. So I can answer it based on probably how it should be, but how it currently is is nobody knows. And because we’re lagging severely behind regulation and we’re lagging severely behind policy and laws, that helps clearly demarcate that. We’re probably going to learn through trial and error.
But I think that’s also why, say, a podcast like this is so important because if the people who would be affected, which is all of us, not just those of us in the industry, all of us in the world have no opinion or have no say in how this policy is being shaped, we’re just going to be on the disadvantaged end of where the law lies.
So I think what makes sense is a sensible demarcated shared responsibility model where there’s responsibility at the individual level, if you were the user who made the AI tool, and the end user who was using something that was made using generative AI, it’s their responsibility on both ends. And then there’s organizational level things, and the actual people who make the tools and the models and then their responsibility. And I mean, cynically, I’d say whoever has the most money to protect themselves from policy being written against their interests is where it might lie if we don’t pay close attention to how the laws are being shaped around it.
One thing that’s a little promising is that the EU has been imposing, or at least formulating laws, and I don’t really know how far the enforcement has got in the last few years. And one of them is the European Union AI Act, which talks about different levels of risk. It talks about what stuff that we just are saying banned, what stuff that is very strictly regulated that’s high risk. There’s some transparency risk level that they’ve come up with, and then things that they’re saying, okay, well, this other stuff is really minimal risk and low risk, so we don’t really have to apply a lot of regulation.
And again, we know that regulation is kind of the bare minimum, that’s what you’re forced to adhere to. And so that doesn’t even really demarcate what’s appropriate. But really at an individual level, I think, are you able to communicate the appropriate system intent and the types of systems that we’re making and whether we’re paying attention to system design and UI design. And when you’re using say domain experts, or maybe we just go to a place where a lot of things are domain experts only and we don’t actually have software engineers in that loop, then for them to also understand their responsibility and how data and systems can affect people.
And then at the organizational level, the responsibility of software architecture governance is important. That’s really important at the individual level also, that’s the actual making of the software architecture. But the governance of do we just completely throw out whole useful, sensible architectural decisions because we’re not paying close enough attention to that, that stuff is really important at the organizational level. And then all the regulatory compliance stuff that organizations have to adhere to now, whether they use AI tools or not, the fact is we’re just kind of losing sight of what our code bases are doing.
So the additional step of ensuring that we are actually adhering to the things that we pretty easily knew in the past that we were. And then the AI tool providers themselves. Every time a new model comes up, even the next version of the same model, we see so much changes within that, and then that also can downstream change systems that were reliant on how that model was working or queries that were reliant on how that model was working.
And that responsibility I think is something that we as people need to make sure that our AI tool providers understand that just providing a fun tool does not end their responsibility. If their tools make up stuff, if their tools miss things, just the fact that we mentioned it and the tool forgot it doesn’t absolve us or the tool of that responsibility.
So one thing that’s a really typical example is when we’re doing development using generative AI tools, we’ve got to make sure that we specify all of the constraints that we really care about. And we know that even some of the best tools will take a subset of those constraints, but then will ignore a bunch of others. And that’s not optional when you’re making production level software and software that actually impacts people’s lives.
So I think what is going to be needed is more regulation and policy there. But right now, at least the way it is in the US, there really isn’t much on the books. So that’s how I see it being done, but we don’t have anything that is forcing people to take responsibility at any of those stages right now.
Daniel Smith: To build on that a bit more, can you talk about the obligations and responsibilities that developers have when it comes to reviewing and testing and documenting and maintaining code produced through vibe coding?
Shreya Kumar: Absolutely. And I think this is the part that’s really clear, which is that obligation is the same as it was when we were doing it without generative AI tools. So the pre-vibe coding era, a developer’s responsibility was really clearly set up, and that responsibility hasn’t changed. The buck still stops with the person who technically made the code, even if they used a tool to make a lot of it.
And in doing that, I find that the systems that I’ve made, if I’m not reading every line of code, which I’m so happy to not have to because I’m like, okay, I know how to do this. I just need it done faster than how much time I would take to do it. And I love that efficiency that comes with it. But I’m also then very disconnected with what software architectural decisions have been made different from what I asked for them to be.
And so in software development, especially using AI coding tools, we need to intentionally reintroduce all of those steps if we aren’t already. So all the steps like making sure our specification is appropriately comprehensive, making sure that we have really good test driven development set up, our requirements have tests associated with it, they’re specified enough that our tests make sense. We write some of the system interfaces and contracts. We make major decisions about what the architecture should be based not just on what’s fast and easy to build, but also on, okay, well, what about later when we’re going to need this for 100,000 users a day? What about later when we’re going to need this for a separate authentication system that we’ll need to plug in a different way?
So understanding the ways that systems traditionally grow. And so the only thing that’s missing is us checking that we’re doing that. All of the things that for 20 plus years I’ve known is a software engineer’s responsibility, all those remain the same. It’s just that we have tools that help us do some of those steps faster, but then that means that I have to go back and double check. So my ability to see the delta between my imagined software architecture and the actual software architecture, the same way that we would measure technical debt before, we just have to be so much more conscious of the technical debt that we accumulate when we’re not even reading the code closely anymore, closely or at all, depending on different parts of the industry.
Daniel Smith: So what I’m hearing is, obviously with the rapid changes that AI is showing, there’s a lot of new considerations for software engineers and how to approach software engineering in a responsible and ethical way. But then the other part of it is just reinforcing existing standards and norms. So with that in mind and looking ahead, how might vibe coding change the skills people need to create technology responsibly and what resources would you recommend for listeners who want to learn more?
Shreya Kumar: Well, also a really great question, mainly because I don’t really have an answer to the second part of it yet, which is what resources really exist. Because the resources are all over the place, mainly because we’re sitting at the top of an explosion as it happens. So I think there’ll be resources that we can rely on better, but some of the old resources on what are the major required ways to build software so that it gets rigorously tested, so that it gets built to specification, so that it gets built and is well tested, not just at the unit testing level, but also usability and for non-functional requirements, all of that stuff is still there in our old ways of doing software engineering.
That stuff remains the same. It’s just the steps get faster because you don’t have to spend four months developing this thing anymore. The module can be made in weeks. And then you can spend our time, our human capital, on ensuring that it’s made correctly, going back and asking it to fix itself. And then as we do that, if we develop different types of coding agents, they get better at holding themselves accountable to it as well. But you do still need so much human intervention to say, oh, okay, well, I created this really great refactoring agent, and all it does is keep shuffling my code base back and forth, back and forth because it doesn’t really keep track of why we made this change in the first place.
So I think so much of the old ways of being accountable still count. The steps get faster because our syntax learning and programming language and platform learning can be faster, but not replaced. I do still think fun vibe coding for a little personal project, maybe no skill is required. But actually software development, I do still think that the people looking at assessing the systems that are being made need to know what a wrong system looks like because the wrong and the right requirements being met look the same if you don’t know what to look for.
So I think the major shift in skills is that you can get to pretty substantial software development with less skill mastery, but still some substantial knowledge. So what used to take three and a half years before someone could actually understand how software engineering works, because our students had to build so many skills in so many different areas to even be able to apply all those things together, that can be cut down to first year, second year students actually engaging in meaningful software development and understanding and realizing their responsibilities both for correctness and for ethical software development much earlier.
So some of the knowledge is still valid from before. The steps of how to do that have become faster. But then we have to reinsert, okay, now go and find ways that you understand the code base. Which one of the ways that I’ve been doing that is if I make a tool that’s vibe coded, not well developed, then I take extra steps to say, okay, well now tell me what the software architecture is for this system in these diagrams, make the class diagram for me, make the swim lane diagram for this process. And then from that reverse engineer what should have been made and then go and remake those. So just that cycle has become faster, but the steps are still the same. And I’d even say you have to be more conscious of those steps because they’re easy to miss if no one’s holding us accountable.
Daniel Smith: I think that’s a wonderful place to leave our conversation for today. So thank you again, Shreya.
Shreya Kumar: Thank you. Thank you for having me, Daniel.
Daniel Smith: If you enjoyed today’s conversation, I encourage you to check out CITI Program’s other podcasts, courses, and webinars. As technology evolves, so does the need for professionals who understand the ethical responsibilities of its development and use. That is why we developed our new Tech Ethics training solution. This new offering brings together practical, thoughtfully designed courses to help professionals navigate ethical and regulatory challenges with confidence. The courses cover responsible AI, software as a medical device in clinical decision support systems, big data and data science, data management, software development, and more. Check out the link in this episode’s description to learn more.
And I just want to give a last special thanks to our line producer, Evelyn Fornell, and production and distribution support provided by Raymond Longaray and Megan Stuart. And with that, I look forward to bringing you all more conversations on all things tech ethics.
How to Listen and Subscribe to the Podcast
You can find On Tech Ethics with CITI Program available from several of the most popular podcast services. Subscribe on your favorite platform to receive updates when episodes are newly released. You can also subscribe to this podcast, by pasting “https://feeds.buzzsprout.com/2120643.rss” into your your podcast apps.
Recent Episodes
Meet the Guest
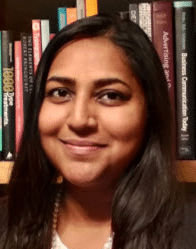
Shreya Kumar, PhD – University of Notre Dame
Dr. Shreya Kumar is an Associate Teaching Professor in Computer Science and Engineering at the University of Notre Dame, Indiana. Drawing on software industry experience in the US, UK and India, she now researches the ethical implications of computing technology and its curricular placement.
Meet the Host
Daniel Smith, Director of Content and Education and Host of On Tech Ethics Podcast – CITI Program
As Director of Content and Education at CITI Program, Daniel focuses on developing educational content in areas such as the responsible use of technologies, humane care and use of animals, and environmental health and safety. He received a BA in journalism and technical communication from Colorado State University.